The Complete Guide to Cloud Infrastructure Requirements for Large Language Model Workloads
October 2, 2026
How Edge Computing Extends Cloud Infrastructure Capabilities to Remote Locations
October 2, 2026
How Cloud TPU and GPU Instance Selection Impacts Machine Learning Training Time
In the rapidly evolving world of artificial intelligence and machine learning, the choice of cloud infrastructure can significantly influence the speed and efficiency of model training. Selecting between TPU (Tensor Processing Units) and GPU (Graphics Processing Units) instances requires a nuanced understanding of their respective architectures and performance characteristics. This article delves into how cloud TPU and GPU instance selection impacts machine learning training time, providing insights that will empower organizations to make informed decisions in optimizing their machine learning workflows.
Understanding TPUs and GPUs
TPUs and GPUs are specialized hardware accelerators designed to enhance computational performance, particularly for tasks involving large-scale data processing and machine learning model training. TPUs, developed by Google, are optimized for tensor processing, making them particularly effective for neural network training. In contrast, GPUs, which have been around for longer, are versatile processors capable of handling a wide range of tasks, including graphics rendering and parallel computing.
Both TPUs and GPUs can be deployed in cloud environments, enabling organizations to leverage their power without the need for significant capital investment in physical hardware. This flexibility is especially beneficial for enterprises that require scalable solutions for machine learning.
The Architecture of TPUs
TPUs utilize a unique architecture that focuses on matrix operations, which are fundamental to machine learning. They consist of multiple cores, each capable of processing large amounts of data simultaneously. This architecture allows TPUs to excel in training deep learning models, particularly those based on convolutional neural networks (CNNs) and recurrent neural networks (RNNs).
The Architecture of GPUs
GPUs, on the other hand, feature a more general-purpose architecture that can handle a variety of tasks beyond machine learning. They contain hundreds or thousands of smaller cores designed for parallel processing. This makes them suitable for a wide range of applications, including gaming, scientific simulations, and, of course, machine learning.
Performance Comparison: TPU vs. GPU
When it comes to performance, both TPUs and GPUs have their strengths and weaknesses, which can significantly impact machine learning training times. Below is a comparison table highlighting key performance metrics for TPUs and GPUs:
| Metric | TPU | GPU |
|---|---|---|
| Architecture | Tensor-optimized | General-purpose |
| Training Speed | Faster for large-scale models | Faster for smaller models |
| Memory Bandwidth | High (up to 1.2 TB/s) | Moderate (up to 900 GB/s) |
| Cost Efficiency | More cost-effective for large workloads | Cost-effective for varied workloads |
As indicated in the table, TPUs generally outperform GPUs in training large-scale models due to their specialized architecture and high memory bandwidth. However, GPUs may offer better performance for smaller models or tasks that require more versatility.
Factors Affecting Training Time
Several factors can influence the training time of machine learning models when using TPUs or GPUs. Understanding these factors can help organizations optimize their workflows and make better choices regarding instance selection.
1. Model Complexity
The complexity of the machine learning model directly impacts training time. More complex models with a higher number of parameters typically require longer training times, regardless of the hardware used. For instance, deep learning models with multiple layers may benefit more from the specialized architecture of TPUs.
2. Dataset Size
The size of the dataset also plays a crucial role. Large datasets can lead to increased training times, especially if the hardware lacks sufficient memory bandwidth. TPUs, with their high memory bandwidth, are often better suited for handling large datasets effectively.
3. Hyperparameter Tuning
Hyperparameter tuning is a critical step in machine learning that can significantly affect training time. The choice of hyperparameters can impact model convergence speed and overall performance. Organizations should consider using automated hyperparameter tuning tools to streamline this process.
4. Batch Size
The batch size used during training can also impact training times. Larger batch sizes can lead to faster training times but may require more memory. TPUs are often able to handle larger batch sizes more efficiently than GPUs.
5. Parallelization
Efficiently parallelizing training tasks can significantly reduce training time. TPUs are designed for high levels of parallelism, which can benefit organizations running multiple training jobs simultaneously.
Best Practices for Instance Selection
Choosing the right instance type is crucial for optimizing training times. Here are some best practices to consider when selecting between TPU and GPU instances:
1. Assess Your Model Requirements
Understanding the specific requirements of your machine learning model is essential. If your model is large and complex, TPUs may offer significant advantages in terms of training speed.
2. Evaluate Dataset Characteristics
Consider the size and characteristics of your dataset. For large datasets, TPUs can provide better performance due to their high memory bandwidth.
3. Experiment with Different Instance Types
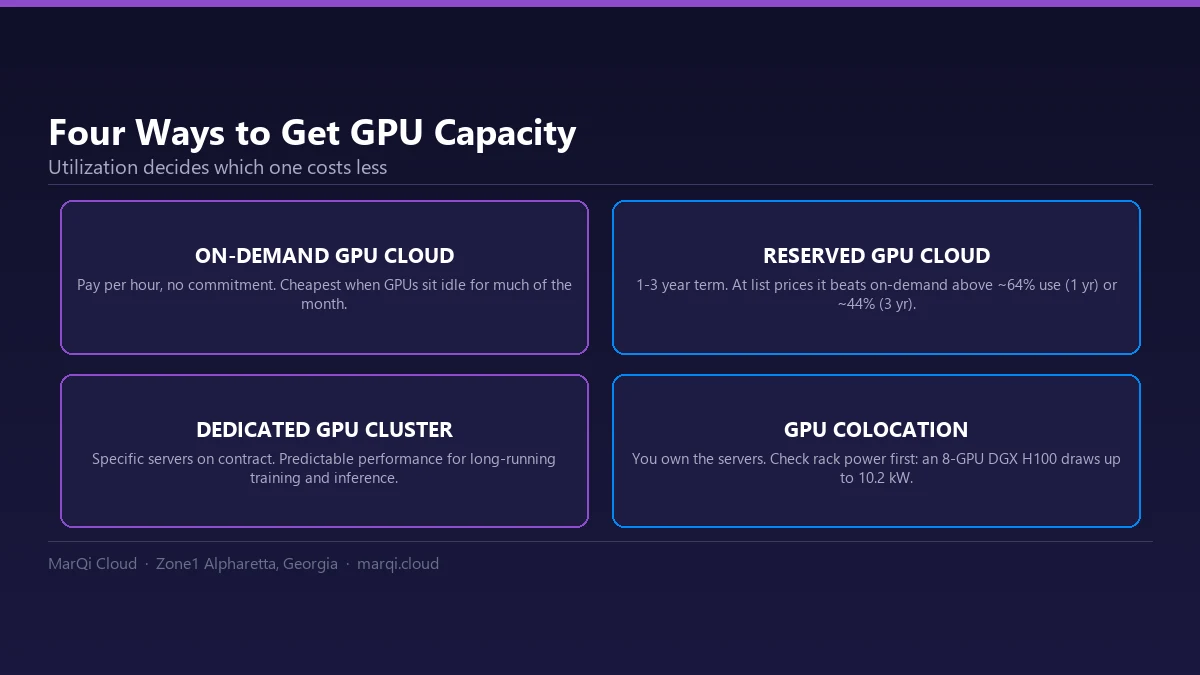
Don’t hesitate to experiment with both TPU and GPU instances to determine which provides optimal performance for your specific workloads. Many cloud providers, including MarQi Cloud, offer flexible pricing models that allow organizations to test different instances without long-term commitments.
4. Monitor Performance Metrics
Regularly monitor performance metrics during training to identify any bottlenecks. Tools for monitoring and analyzing resource usage can help you make informed decisions about instance selection.
5. Consider Managed Services
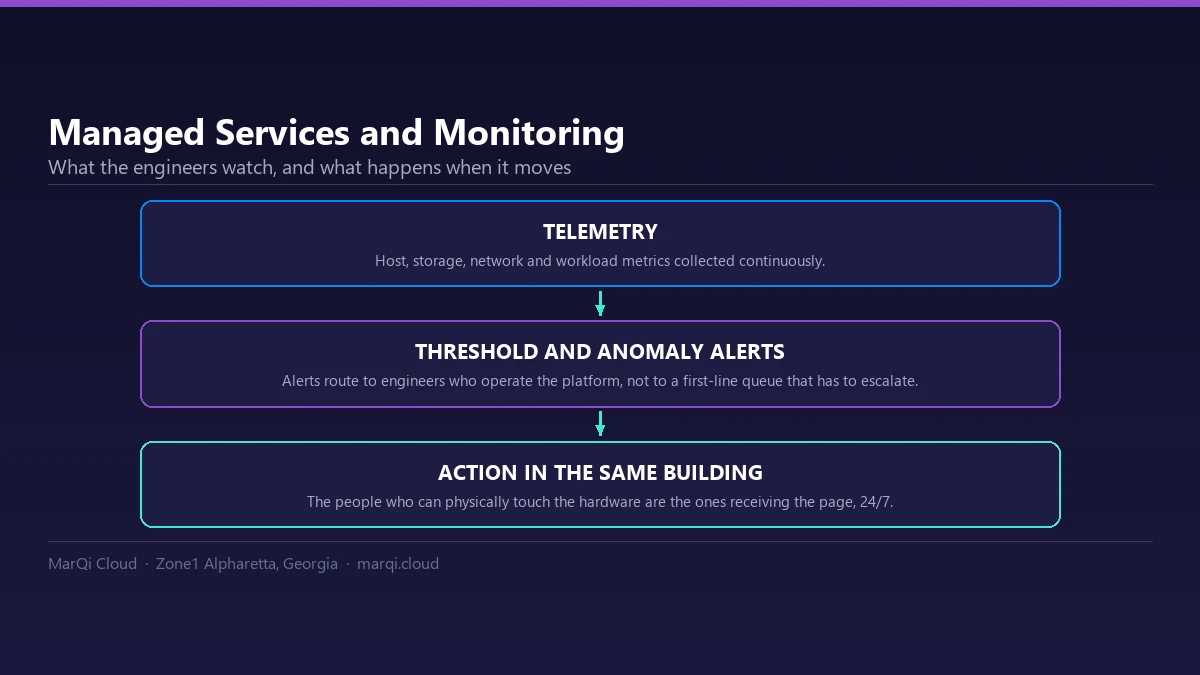
Utilizing managed services can streamline the deployment process and ensure optimal configuration of your cloud infrastructure. MarQi Cloud offers white-glove managed services to help organizations optimize their cloud environments for machine learning.
Example Scenarios
The scenarios below are illustrative examples of how instance selection affects training time; they are not reports from specific companies:
Scenario 1: Image Classification with Convolutional Neural Networks
A team training a large image classification model on millions of images can use TPUs, whose matrix units suit the dense tensor operations in convolutional networks, to shorten each training run and iterate on the model more often.
Scenario 2: Natural Language Processing with RNNs
A team training smaller sequence models may find GPUs the better fit, because their flexibility with varied operations and batch sizes matters more than raw matrix throughput at that scale; matching the instance to model size and complexity keeps training time and cost in check.
Frequently Asked Questions
1. What is the primary difference between TPUs and GPUs?
TPUs are specifically designed for tensor processing, making them ideal for deep learning tasks, while GPUs are more versatile and can handle various computing tasks.
2. How do I choose between TPU and GPU for my machine learning project?
Consider your model’s complexity, dataset size, and training requirements. Experimenting with both types can also help identify the best fit.
3. Are TPUs more cost-effective than GPUs?
TPUs can be more cost-effective for large-scale workloads due to their specialized architecture and high memory bandwidth.
4. What factors influence machine learning training time?
Factors include model complexity, dataset size, hyperparameter tuning, batch size, and parallelization.
5. Can I use TPUs for smaller models?
While TPUs can be used for smaller models, GPUs may provide better performance and flexibility in those cases.
6. How can I optimize my machine learning workflow?
Monitor performance metrics, experiment with different instance types, and consider using managed services for optimal configuration.
7. What role does batch size play in training time?
Larger batch sizes can reduce training time but may require more memory; TPUs typically handle larger batch sizes more efficiently.
8. Where can I find more information about machine learning on cloud platforms?
For detailed insights, refer to resources from authoritative sites like NIST or AAAI.